
IT Operations
& Service
We monitor, maintain and fix your IT 24/7/365, so your team can focus on growing the business. Delivered under a contractual SLA.
Three operational domains
One operations partner, three clear areas of responsibility
We organise 24/7 operations into three domains, so it is always clear who is responsible for security, infrastructure and application reliability.
- SOC
Security
We monitor security events (SIEM/XDR), assess threats, respond to incidents and keep systems patched against known vulnerabilities.
Related services
- NOC
Network & Cloud Infrastructure
We monitor networks, servers and cloud services 24/7/365, resolve incidents within the SLA and escalate them to the right engineer.
Related services
- SRE
Application Reliability
We measure service availability against SLOs, manage error budgets, test recovery and analyse root causes, so business-critical applications stay available.
Related services
Our operational processes are inspired by NATO discipline and methodology and adapted to the requirements of business-critical IT environments.
Our responsibility
We take ownership of your everyday IT
Operations is more than fixing what breaks. We continuously monitor, analyse and improve your systems so they run stable and secure. Our NOC and SOC run this cycle every day, around the clock, with contractual accountability:
- 01
We see
We watch your systems 24/7 and catch problems before your customers do.
- 02
We understand
We filter out the noise and find the cause and the business impact.
- 03
We act
We resolve incidents within the SLA, nights and weekends included.
- 04
We improve
We turn every incident into an improvement, so it does not happen again.
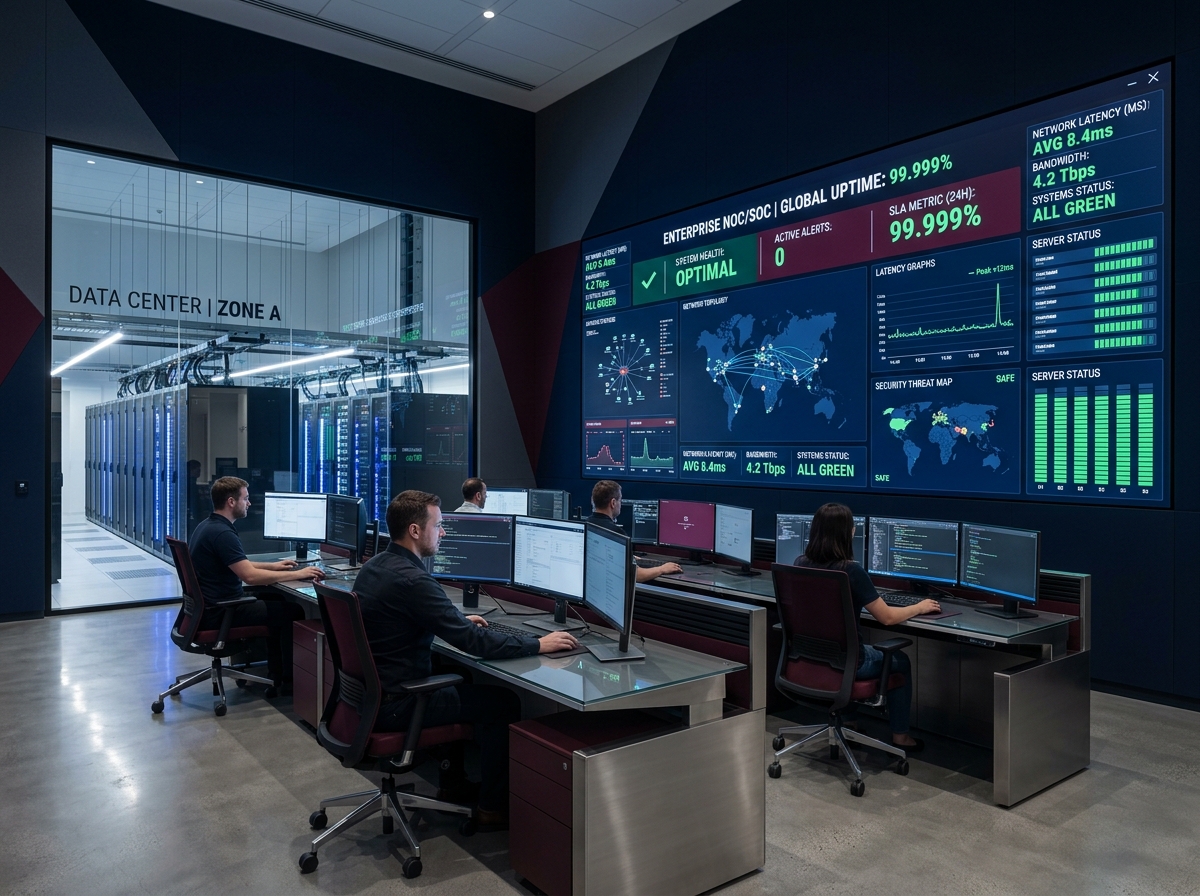
How we see
You hear about a problem from us, not from your customers. Our NOC and SOC watch your systems around the clock and catch deviations before they turn into incidents.
- 24/7/365 monitoring of systems, network and services
- Security event monitoring (SIEM/XDR)
- Service availability measured against SLOs and SLAs
- Monthly reports with telemetry data and SLA performance
How we understand
Not every alert is an incident. Our engineers filter out the noise, find the cause and understand the business impact.
- Alert correlation and noise filtering
- Incident prioritisation by business impact
- Root-cause analysis, not just treating symptoms
- Threat assessment in the SOC
How we act
When something happens, we act within the SLA instead of waiting for the working day to start.
- P1 response within 15 minutes on the Mission Critical tier
- A dedicated emergency engineering line
- Security patching and vulnerability remediation
- Data recovery within agreed RTO and RPO
How we improve
Every incident is a lesson. We analyse root causes and make changes so it does not happen again.
- Root-cause analysis (RCA) within 24 hours
- Error budgets and SLO management
- Regular cyber-hygiene and compliance audits
- A monthly service improvement plan
Experience in practice
Contractual SLA Tiers & Response Parameters
Standard Business
8/5- Response: < 2 hours (P1)
- Business days: 08:00 - 18:00
- Regular system audits
Enterprise 24/7
24/7- Response: < 30 minutes (P1)
- 24/7/365 NOC monitoring
- Dedicated phone line
Mission Critical
TOP TIER- Response: < 15 minutes (P1)
- Twin NOC & SOC in 3 shifts
- Service credits subject to contractual terms
From our project experience
Frequently asked questions
How fast do you respond to an incident?
On the Mission Critical tier, within 15 minutes for P1 incidents, 24/7/365.
What does the SLA include?
Response times, monitoring, incident resolution and regular reporting. You choose the tier by how critical the system is.
Do you also run systems from other vendors?
Yes. Takeover starts with an audit and getting the documentation in order.
How do we see the service quality?
In monthly reports with telemetry data and SLA performance.